Briefly
- Veo 3.1 introduces full-scene audio, dialogue, and ambient sound era.
- The launch follows Sora 2’s fast rise to 1 million downloads inside 5 days.
- Google positions Veo as a professional-grade different within the crowded AI video market.
Google released Veo 3.1 today, an up to date model of its AI video generator that provides audio throughout all options and introduces new enhancing capabilities designed to offer creators extra management over their clips.
The announcement comes as OpenAI’s competing Sora 2 app climbs app retailer charts and sparks debates about AI-generated content material flooding social media.
The timing suggests Google desires to place Veo 3.1 because the skilled different to Sora 2’s viral social feed strategy. OpenAI launched Sora 2 on September 30 with a TikTok-style interface that prioritizes sharing and remixing.
The app hit 1 million downloads inside 5 days and reached the highest spot in Apple’s App Retailer. Meta took an analogous strategy, with its personal type of digital social media powered by AI movies.
Customers can now create movies with synchronized ambient noise, dialogue, and Foley results utilizing “Elements to Video,” a software that mixes a number of reference photographs right into a single scene.
The “Frames to Video” characteristic generates transitions between a beginning and ending picture, whereas “Prolong” creates clips lasting as much as a minute by persevering with the movement from the ultimate second of an present video.
New enhancing instruments let customers add or take away parts from generated scenes with automated shadow and lighting changes. The mannequin generates movies in 1080p decision at horizontal or vertical side ratios.
The mannequin is obtainable by Circulate for client use, the Gemini API for builders, and Vertex AI for enterprise prospects. Movies lasting as much as a minute may be created utilizing the “Prolong” characteristic, which continues movement from the ultimate second of an present clip.
The AI video era market has grow to be crowded in 2025, with Runway’s Gen-4 mannequin focusing on filmmakers, Luma Labs providing quick era for social media, Adobe integrating Firefly Video into Inventive Cloud, and updates from xAI, Kling, Meta, and Google focusing on realism, sound era, and immediate adherence.
However how good is it? We examined the mannequin, and these are our impressions.
Testing the mannequin
If you wish to strive it, you’d higher have some deep pockets. Veo 3.1 is at the moment the costliest video era mannequin, on par with Sora 2 and solely behind Sora 2 Professional, which prices greater than twice as a lot per era.
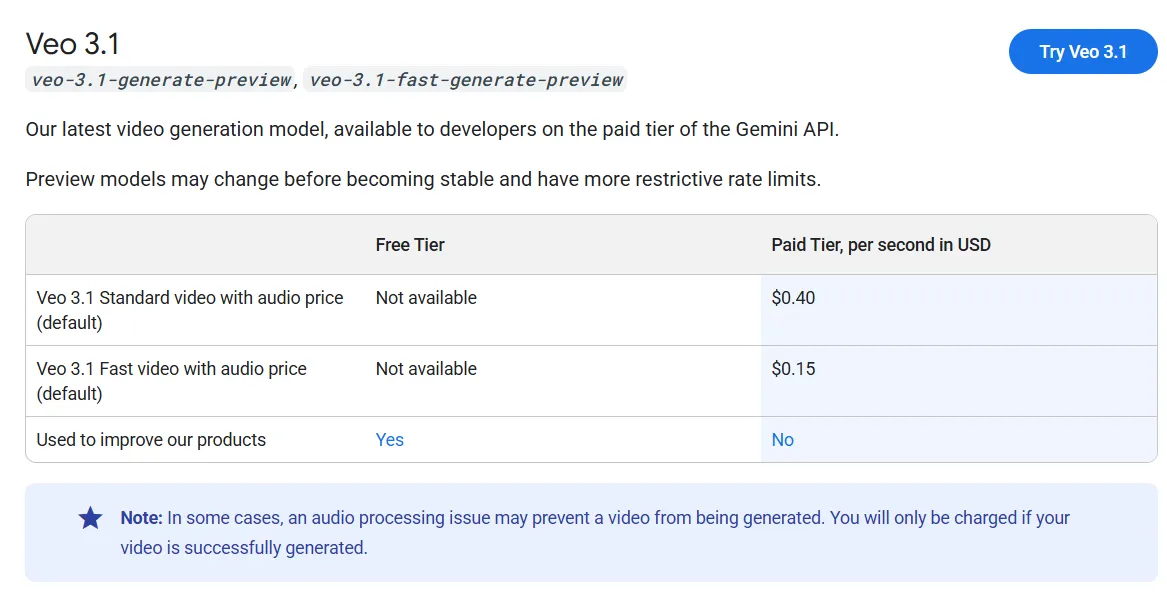
Free customers obtain 100 month-to-month credit to check the system, which is sufficient to generate round 5 movies monthly. By the Gemini API, Veo 3.1 prices roughly $0.40 per second of generated video with audio, whereas a quicker variant known as Veo 3.1 Quick prices $0.15 per second.

For these prepared to make use of it at that value, listed here are its strengths and weaknesses.
Textual content to Video
Veo 3.1 is a particular enchancment over its predecessor. The mannequin handles coherence nicely and demonstrates a greater understanding of contextual environments.
It really works throughout completely different kinds, from photorealism to stylized content material.
We requested the mannequin to blend a scene that began as a drawing and transitioned into live-action footage. It dealt with the duty higher than another mannequin we examined.
With none reference body, Veo 3.1 produced higher leads to text-to-video mode than it did utilizing the identical immediate with an preliminary picture, which was stunning.
The tradeoff is motion velocity. Veo 3.1 prioritizes coherence over fluidity, making it difficult to generate fast-paced motion.
Parts transfer extra slowly however preserve consistency all through the clip. Kling nonetheless leads in fast motion, though it requires extra makes an attempt to realize usable outcomes.
Picture to Video
Veo constructed its repute on image-to-video era, and the outcomes nonetheless ship—with caveats. This seems to be a weaker space within the replace. When utilizing completely different side ratios as beginning frames, the mannequin struggled to take care of the coherence ranges it as soon as had.
If the immediate strays too removed from what would logically observe the enter picture, Veo 3.1 finds a technique to cheat. It generates incoherent scenes or clips that jump between locations, setups, or solely completely different parts.
This wastes time and credit, since these clips cannot be edited into longer sequences as a result of they do not match the format.
When it really works, the outcomes look improbable. Getting there’s half ability, half luck—largely luck.
Parts to Video
This characteristic works like inpainting for video, letting customers insert or delete parts from a scene. Do not anticipate it to take care of good coherence or use your precise reference photographs, although.
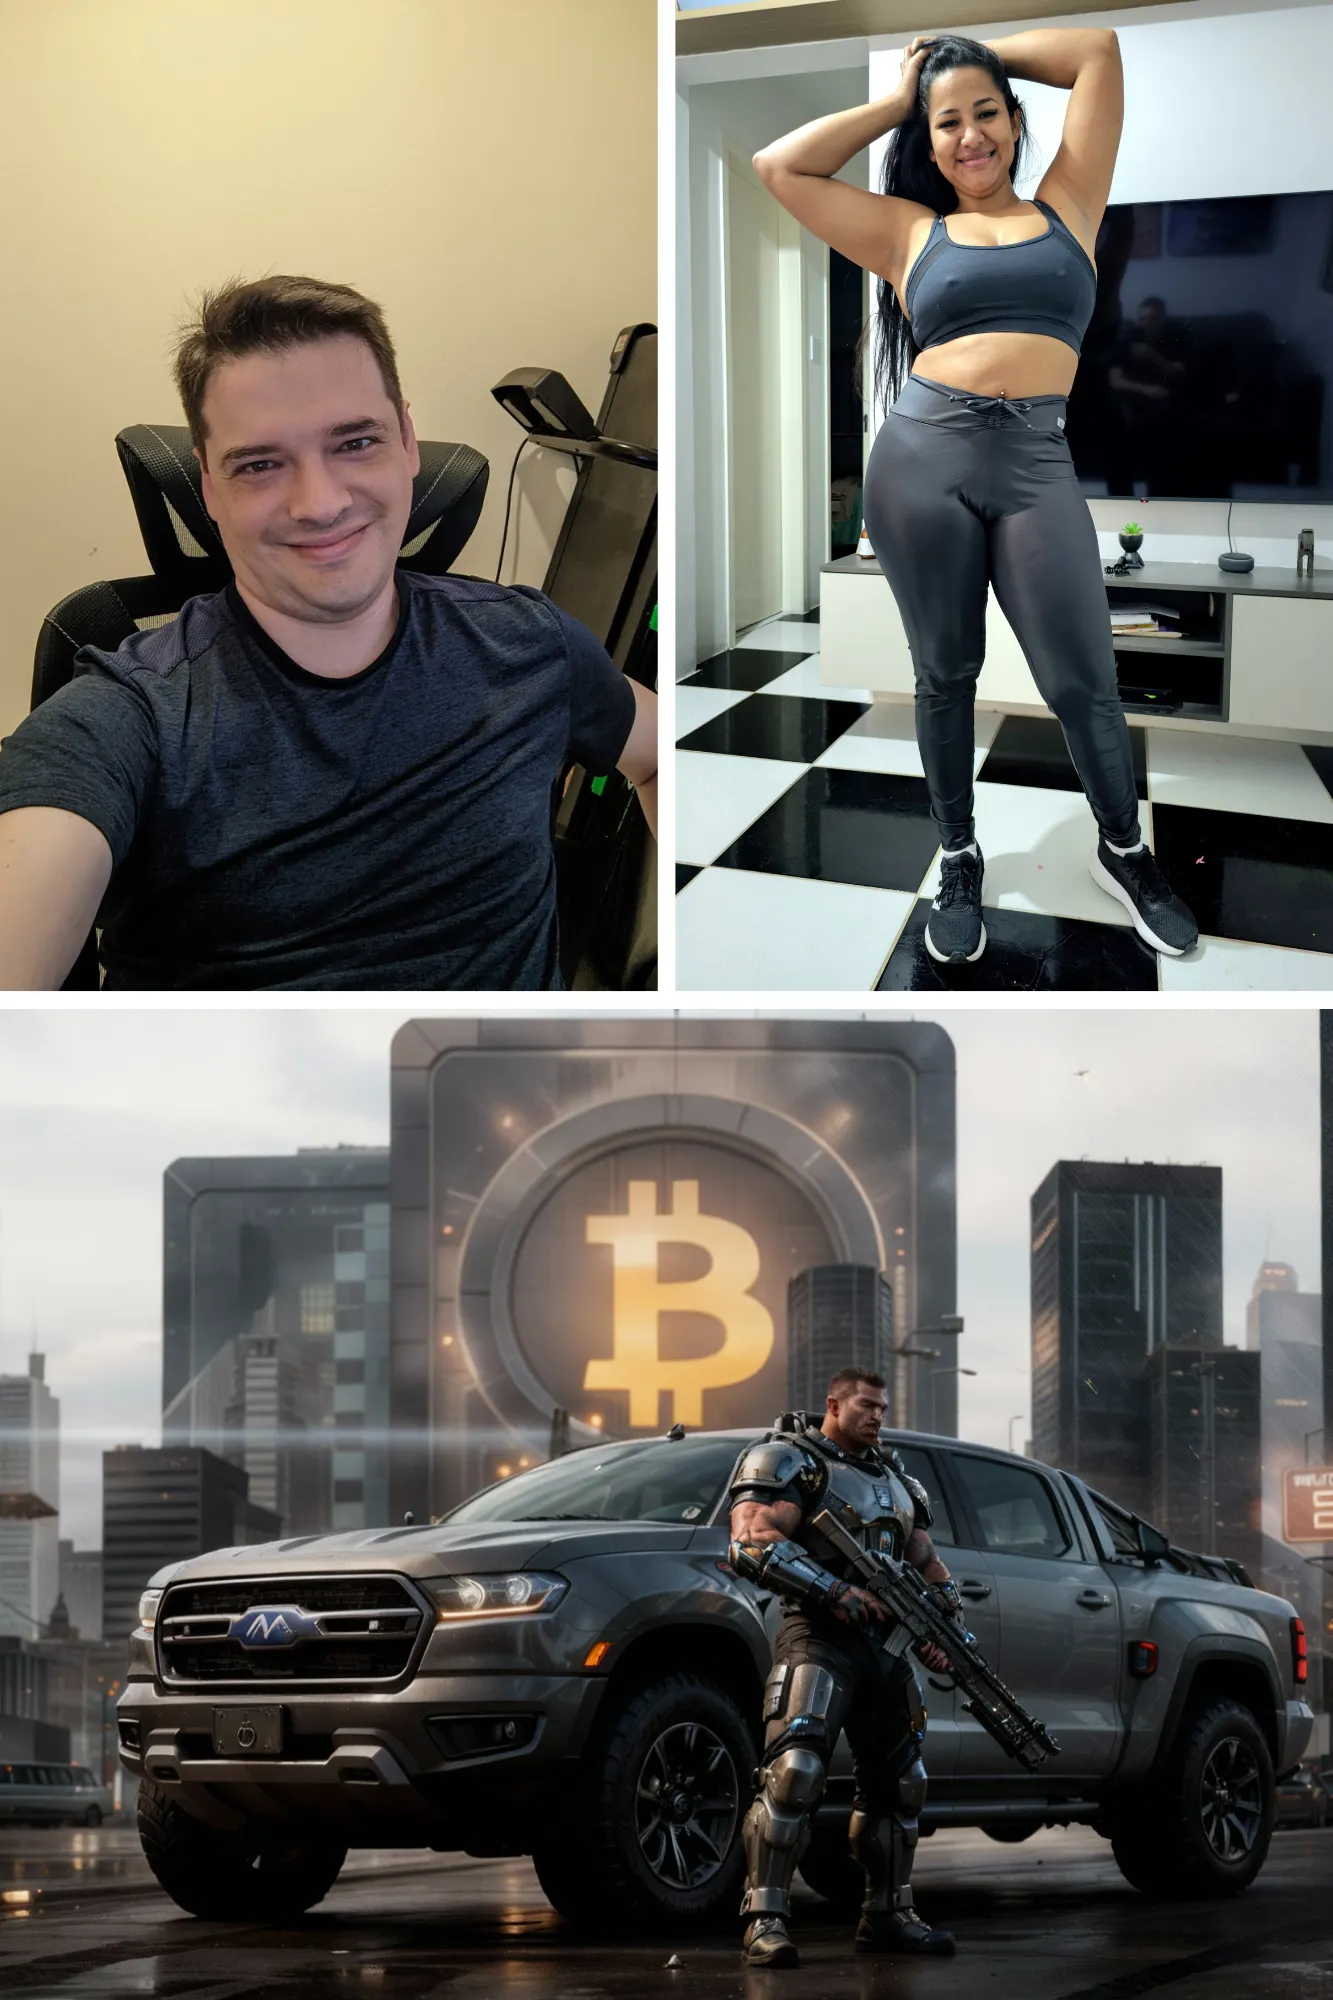
For instance, the video beneath was generated utilizing these three references and the immediate: a person and a lady bump into one another whereas working in a futuristic metropolis, the place a Bitcoin signal hologram is rotating. The person tells the girl, “QUICK, BITCOIN CRASHED! WE MUST BUY MORE!!

As you can see, neither town nor the characters are literally there. Nevertheless, characters are sporting the garments of reference, town resembles the one within the within the picture, and issues painting the thought of the weather, not the weather themselves.
Veo 3.1 treats uploaded parts as inspiration somewhat than strict templates. It generates scenes that observe the immediate and embrace objects that resemble what you offered, however do not waste time making an attempt to insert your self right into a film—it will not work.
A workaround: use Nanobanana or Seedream to add parts and generate a coherent beginning body first. Then feed that picture to Veo 3.1, which is able to produce a video the place characters and objects present minimal deformation all through the scene.
Textual content to Video with Dialogue
That is Google’s promoting level. Veo 3.1 handles lip sync higher than another mannequin at the moment obtainable. In text-to-video mode, it generates coherent ambient sound that matches scene parts.
The dialogue, intonation, voices, and feelings are correct and beat competing fashions.
Different turbines can produce ambient noise, however solely Sora, Veo, and Grok can generate precise phrases.
Of these three, Veo 3.1 requires the fewest makes an attempt to get good leads to text-to-video mode.
Picture to Video with Dialogue
That is the place issues collapse. Picture-to-video with dialogue suffers from the identical points as normal image-to-video era. Veo 3.1 prioritizes coherence so closely that it ignores immediate adherence and reference photographs.
For instance, this scene was generated utilizing the reference proven within the parts to video part.
As you’ll be able to see, our check generated a totally completely different topic than the reference picture. The video high quality was wonderful—intonation and gestures have been spot-on—nevertheless it wasn’t the individual we uploaded, making the end result ineffective.
Sora’s remix characteristic is your best option for this use case. The mannequin could also be censored, however its image-to-video capabilities, reasonable lip sync, and concentrate on tone, accent, emotion, and realism make it the clear winner.
Grok’s video generator is available in second. It revered the reference picture higher than Veo 3.1 and produced superior outcomes. Here is one generation utilizing the identical reference picture and immediate.
If you happen to do not need to cope with Sora’s social app or lack entry to it, Grok is likely to be your only option. It is also uncensored however moderated, so in case you want that exact strategy, Musk has you lined.
Typically Clever E-newsletter
A weekly AI journey narrated by Gen, a generative AI mannequin.
You might also like
More from Web3
Coinbase Files to List Single-Stock Perps on Apple, Tesla and Nvidia
Briefly Coinbase filed with the CFTC by means of Coinbase Derivatives to record single-stock perpetual futures within the US, searching …
Zcash Is Running—Devs Want to Make It Faster
In short Zcash builders are focusing on Nov. 5 to activate NU7, an improve that cuts block time—the interval between …
OpenAI Models Are Writing Their Own Jailbreak Instructions—And Sometimes Obeying Them
In short OpenAI revealed a brand new misalignment reporting framework alongside six experiences documenting regarding mannequin habits it discovered over …