

Ought to this assist ticket go to billing or engineering? Is that this agent’s subsequent step protected to run? Is that this reply really grounded within the supply paperwork?
After we construct brokers, a giant a part of the work isn’t writing textual content in any respect. It’s making small, bounded selections, again and again. Till now, we have now largely despatched these selections to a giant, general-purpose LLM. That works, however it’s gradual and costly, like hiring a novelist to kind your mail.
Microsoft simply launched a mannequin constructed for precisely this: Microsoft-Determination-1, now obtainable in Microsoft Foundry. I after all went to Foundry to have a look and deploy it. Let’s take a better look!
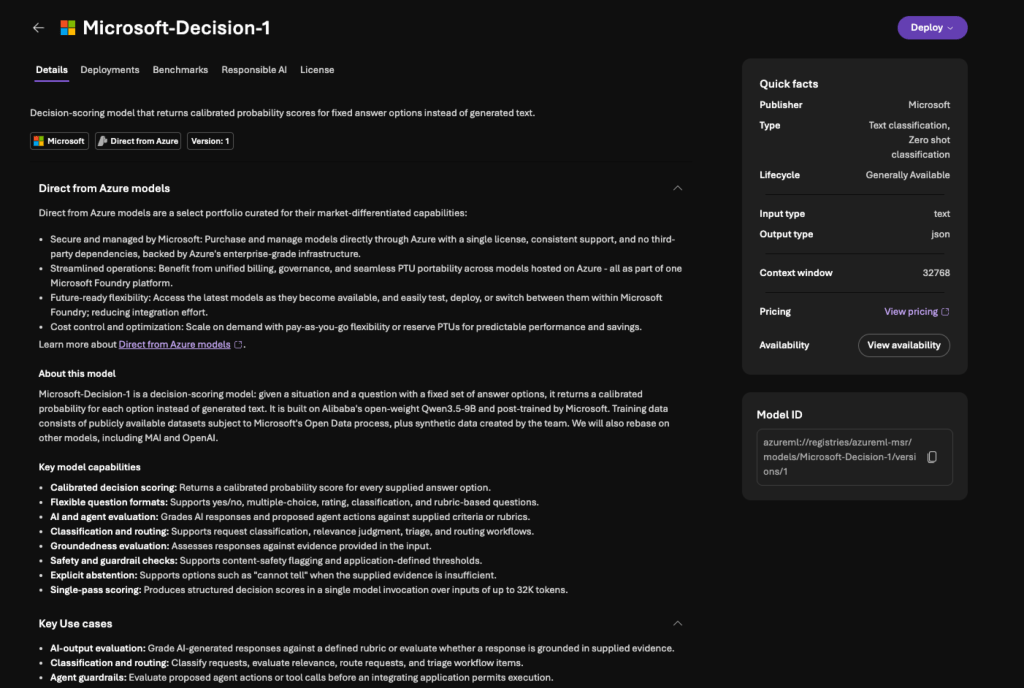
Microsoft-Determination-1 is a decision-scoring mannequin. You give it a scenario, a query and a set set of reply choices. It offers again a calibrated likelihood rating for every choice.
No generated textual content. No chat. No explanations. It returns a quantity your utility can act on instantly.
In Foundry the mannequin card reveals the fundamentals:
- Writer: Microsoft, within the Direct from Azure portfolio
- Lifecycle: Typically Out there, model 1
- Sort: Textual content classification and zero-shot classification
- Enter: textual content. Output: JSON
- Context window: 32,768 tokens
Below the hood, it’s constructed on Alibaba’s open-weight Qwen3.5-9B mannequin and post-trained by Microsoft. Microsoft additionally says it can rebase the mannequin on different fashions, together with MAI and OpenAI. That half is attention-grabbing. Determination-1 is clearly the beginning of a mannequin household, not a one-off launch.
The mannequin handles three sorts of questions:
- Is that this true? A sure/no examine that returns a likelihood from 0 to 1. Instance: “Does this reply promise the client a refund?” These work nicely as gates and filters.
- Which choice is it? One chosen choice plus a likelihood for each choice. Instance: “Which workforce ought to deal with this ticket: billing, engineering or assist?” That is classification and routing.
- How a lot? A place on an ordered scale. Instance: “How extreme is that this incident: beauty, minor, main or important?” This covers rating and grading.
You can even mix a number of questions in a single request. For instance, route a ticket, fee its severity and examine whether or not it’s a repeat contact, multi function name.
There’s additionally specific abstention. You may add an choice like “can not inform” when the enter doesn’t comprise sufficient proof. I actually like this. Forcing a mannequin to choose a solution when it doesn’t know is how quite a lot of AI errors begin.
Brokers chain selections. Microsoft offers an excellent instance: add 100 milliseconds to every of 20 sequential selections and the entire workflow is 2 seconds slower. Now multiply that by hundreds of runs a day.
Then there’s the value: $0.042 per million enter tokens, and output tokens are free. That’s not a typo. For the reason that mannequin solely returns scores, there’s little or no output to pay for anyway.
For agent builders, two makes use of stand out for me:
- Agent guardrails: examine a proposed agent motion or instrument name earlier than your utility lets it run
- Confidence-based automation: automate the clear instances and escalate low-confidence ones to a human
Microsoft additionally shares inner outcomes, for instance from the Copilot workforce utilizing it to measure response high quality, plus its personal benchmark comparisons in opposition to LLMs and different choice fashions. These are vendor numbers, so I’d deal with them as a place to begin. Your personal information is the benchmark that issues.
Getting began is straightforward. Discover Microsoft-Determination-1 within the Foundry mannequin catalog, choose Deploy, give the deployment a reputation and select a deployment sort.
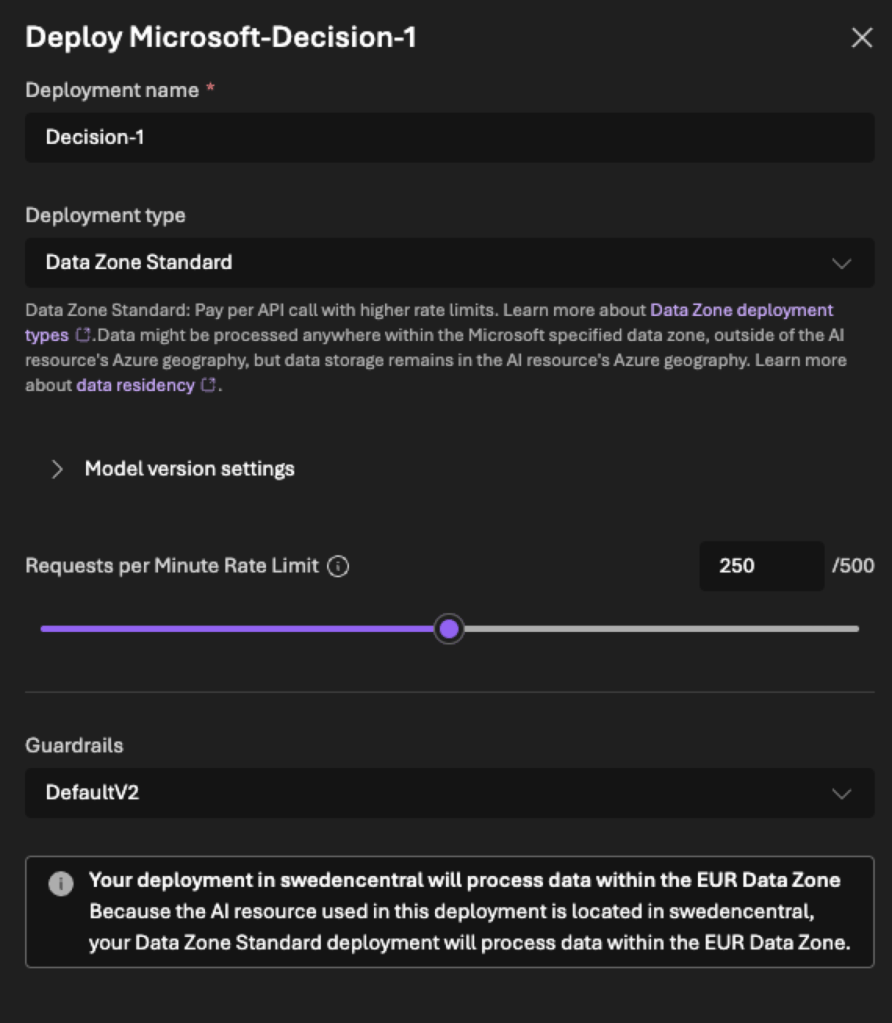
That is the place it will get attention-grabbing for us in Europe. My Foundry useful resource is in Sweden Central, and with Knowledge Zone Commonplace the dialog confirms that processing stays inside the EUR Knowledge Zone. The information may be processed anyplace in that information zone, however storage stays within the useful resource’s Azure geography. Good to see this selection at launch!
The opposite choice is International Commonplace, the place inference may be processed in any supported Azure area. For my very own testing I went with International Commonplace. It’s often cheaper than fashions deployed to a selected information zone, and my check information doesn’t want EU processing. For buyer information, the selection could be very completely different.
The only rule from Microsoft’s documentation: use Determination-1 when your utility wants a number of bounded, typed selections about the identical enter. It’s at its greatest in high-volume workflows the place the appliance acts on a likelihood, a particular choice or a rating, as an alternative of displaying generated textual content to somebody.
Based mostly on Microsoft’s Study, listed here are 5 areas the place the mannequin matches.
- Gates and filters: examine that content material meets a situation earlier than the workflow continues. Does this instrument name contact manufacturing information? Does this doc comprise a immediate injection? Does this assist reply promise a refund?
- Classification and routing: ship tickets, alerts, paperwork or requests to at least one choice from a identified set. Consider the service desk queue that somebody types by hand each morning.
- Rating and prioritization: order incidents, leads, search outcomes or assessment queues on a scale you outline. What ought to the workforce take a look at first?
- Analysis and grading: rating AI output in opposition to a rubric. This one pursuits me rather a lot. As we construct extra brokers, we want a quick and low-cost method to examine their solutions at scale.
- Mannequin, instrument or agent choice: select which mannequin, instrument or agent ought to deal with a request. In multi-agent setups that is the visitors controller.
And the opposite facet: whenever you want content material created, summarized, rewritten or defined, use a generative LLM. The mannequin doesn’t write a rationale. You get a quantity, not a purpose. In case your course of wants to point out why a choice was made, you want one thing extra.
The very best sample, in my view, is a mix. Determination-1 routes or gates the request first, and a generative mannequin then does the precise writing solely the place it’s wanted. Proper mannequin for the suitable job.
A couple of issues I’d examine earlier than utilizing it with actual work:
- Language. Determination-1 is optimized for English and evaluated in additional than 20 different languages. Finnish and Swedish aren’t on that record. The bottom mannequin helps way more languages, however high quality and calibration might fluctuate. For Nordic clients: check with your personal language information first!
- Wording issues. Scores can change relying on the way you phrase questions and order choices, and a badly framed query nonetheless returns a rating. Microsoft’s personal checks present the mannequin to be secure when choices are shuffled, however the documentation nonetheless recommends testing it your self. Use clear, impartial choices and examine the outcomes with your personal information.
- Choices about individuals. Microsoft is evident that the mannequin shouldn’t be the one decision-maker in consequential selections about individuals, akin to employment, credit score, healthcare or authorized issues. Use it for choice assist, with significant human assessment.
- Knowledge location. Select Knowledge Zone Commonplace when your information wants to remain within the EU.
I feel choice fashions will quietly grow to be one of the vital essential constructing blocks in agent architectures. They gained’t make headlines like the subsequent massive frontier mannequin, however they’ll make brokers quicker, cheaper and simpler to regulate.
Model 1 is constructed on Qwen, and Microsoft already plans MAI- and OpenAI-based variations. As a tip for Microsoft: it might be superior to see choice steps like this obtainable instantly in Copilot Studio. Think about a “determine” node with calibrated possibilities and a built-in “can not inform” path! ( wink on the Copilot Studio workforce)
Which choice in your workflows would you hand to a small, quick mannequin first?
Microsoft sources:

Revealed by
I work, weblog and talk about Future Work : AI, Microsoft 365, Copilot, Loop, Azure, and different companies & platforms within the cloud connecting digital and bodily and other people collectively.
I’ve 30 years of expertise in IT enterprise on a number of industries, domains, and roles.
View all posts by Vesa Nopanen
You might also like


More from Metaverse Global

Tampered Ledgers Reported in Europe as CZ Says Hackers Bought the Reseller
Restricted Ledger gadget tampering underscores supply-chain vulnerabilities throughout international {hardware} pockets markets.European researcher’s discovering raises business issues about undisclosed …

Kalshi Probes $173 in Bets That Called Trump’s Press Secretary Pick Katie Zacharia at 1% Odds
Kalshi, a federally regulated prediction market in the USA, is investigating a small cluster of trades that accurately guess …

XRP Ledger Reveals Critical Bug That Could Have Minted XRP Beyond Its 100 Billion Supply
The XRP Ledger (XRPL) has disclosed a vital vulnerability in its cost engine that might have allowed an attacker …