In short
- DeepReinforce launched Ornith-1.0 on June 25 beneath MIT license, purpose-built for AI coding brokers working in actual terminal and repository environments.
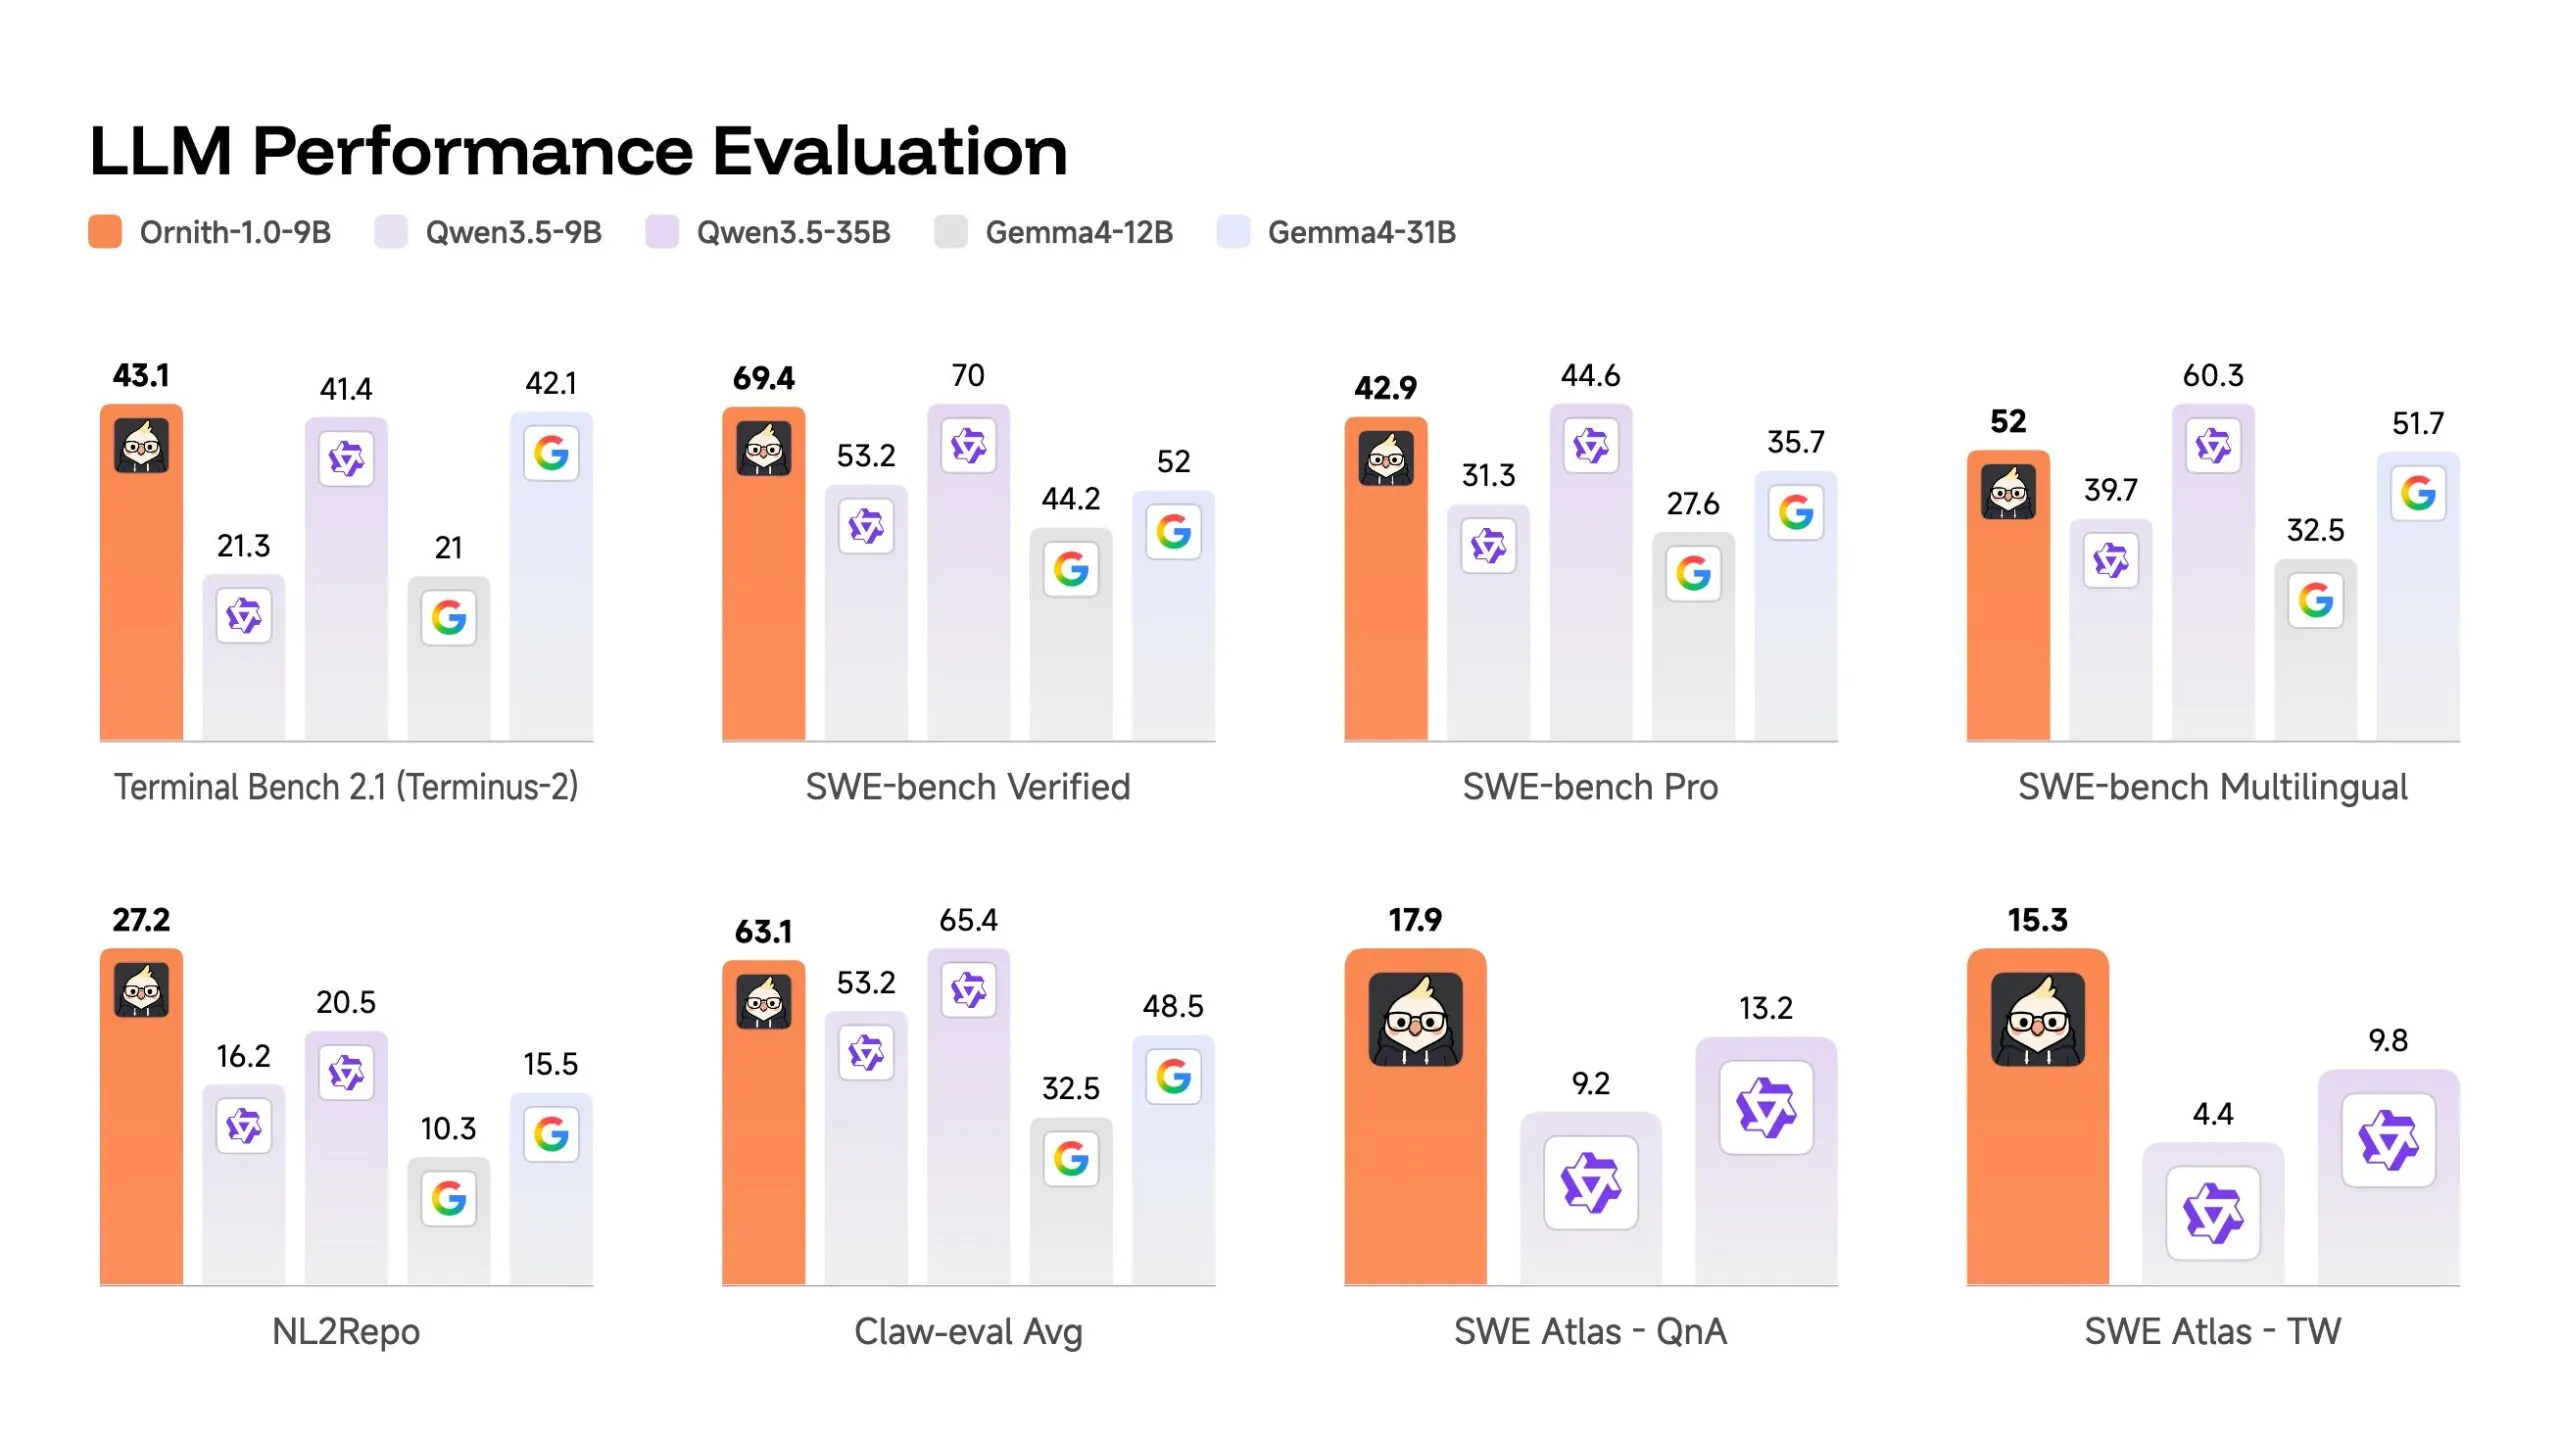
- The 9B variant scores 69.4 on SWE-bench Verified, outperforming Google’s Gemma 4-31B (52.0).
- Ornith’s personal mannequin card warns the fashions could underperform on non-coding duties—they’re wired for developer pipelines, not general-purpose AI conversations.
DeepReinforce, an AI analysis lab beforehand recognized for CUDA-L1 and the IterX code-agent optimization loop, released Ornith-1.0 late final week—a household of open-source coding fashions obtainable on Hugging Face in 4 sizes based mostly on the variety of parameters: 9 billion, 31 billion, 35 billion combination of consultants, and a 397 billion mixture-of-experts flagship, all beneath MIT license with no regional restrictions.
Parameters are principally the variety of dials and configurations a mannequin can deal with on its coaching. The extra parameters, the extra succesful a mannequin is. A 9-billion-parameter mannequin is taken into account small, ok to run on an excellent smartphone, however not able to doing any heavy reasoning job reliably. A 397 billion mannequin is far more succesful, however requires some heavy computing, the type that’s not obtainable on client {hardware}.
The lab describes it as “a self-improving household of open-source fashions specifically for agentic coding duties.” That phrase—agentic—is doing loads of work.
Aloha! 🌺 Meet Ornith-1.0, a household of open-source LLMs specialised for agentic coding.
Ornith-1.0 spans the complete parameter sizes together with 9B Dense, 31B Dense, 35B MoE, and 397B MoE. It achieves state-of-the-art efficiency amongst open-source fashions of comparable measurement on… pic.twitter.com/7g1rmacLps
— Ornith (@ornith_) June 25, 2026
Most AI that folks work together with is conversational: you sort, it responds, the change ends. Agentic AI is totally different—it will get a job and takes actions to finish it with no human guiding every step. In a coding context, meaning an AI that reads information, runs checks, identifies what failed, fixes the code, and loops once more till it is finished.
So Agentic AI means nobody must be on the keyboard for more often than not. That is the entire level. That is additionally the course the place probably the most commercially related progress is going on in 2026—the fashions that may run unsupervised via 20-step dev workflows are value greater than those that write a clear operate on request.
Nevertheless, most massive language fashions are nonetheless designed with human suggestions in thoughts.
How Ornith’s mind works
Most AI coding brokers are paired with a human-designed harness—a hard and fast algorithm for a way the agent buildings its work: when to name a software, easy methods to deal with an error, easy methods to decompose a multi-step downside. Ornith as a substitute “treats the scaffold as a learnable object that co-evolves with the coverage.”
Translation: as a substitute of inheriting another person’s playbook, it develops its personal.
Throughout reinforcement studying, every coaching step occurs in two levels. The mannequin first reads the duty and proposes a refined technique for approaching it. Then it makes use of that technique to generate an answer.
The reward from the end result flows again to each levels—so the mannequin is optimized for writing higher methods, not simply higher code. Try this 1000’s and hundreds of thousands of instances, and task-specific approaches emerge with no human engineering them.
DeepReinforce additionally takes reward hacking severely. If the mannequin can write its personal coaching scaffold, it may theoretically write a scaffold that video games the verifier—touching a file to make it seem like it accomplished a job with out truly doing the work. Three layers of protection block this: the surroundings and take a look at suite are immutable and out of doors the mannequin’s attain, a deterministic monitor flags any try to entry restricted paths or alter verification scripts, and a frozen choose mannequin sits on prime of the automated verifier as a veto.
The numbers
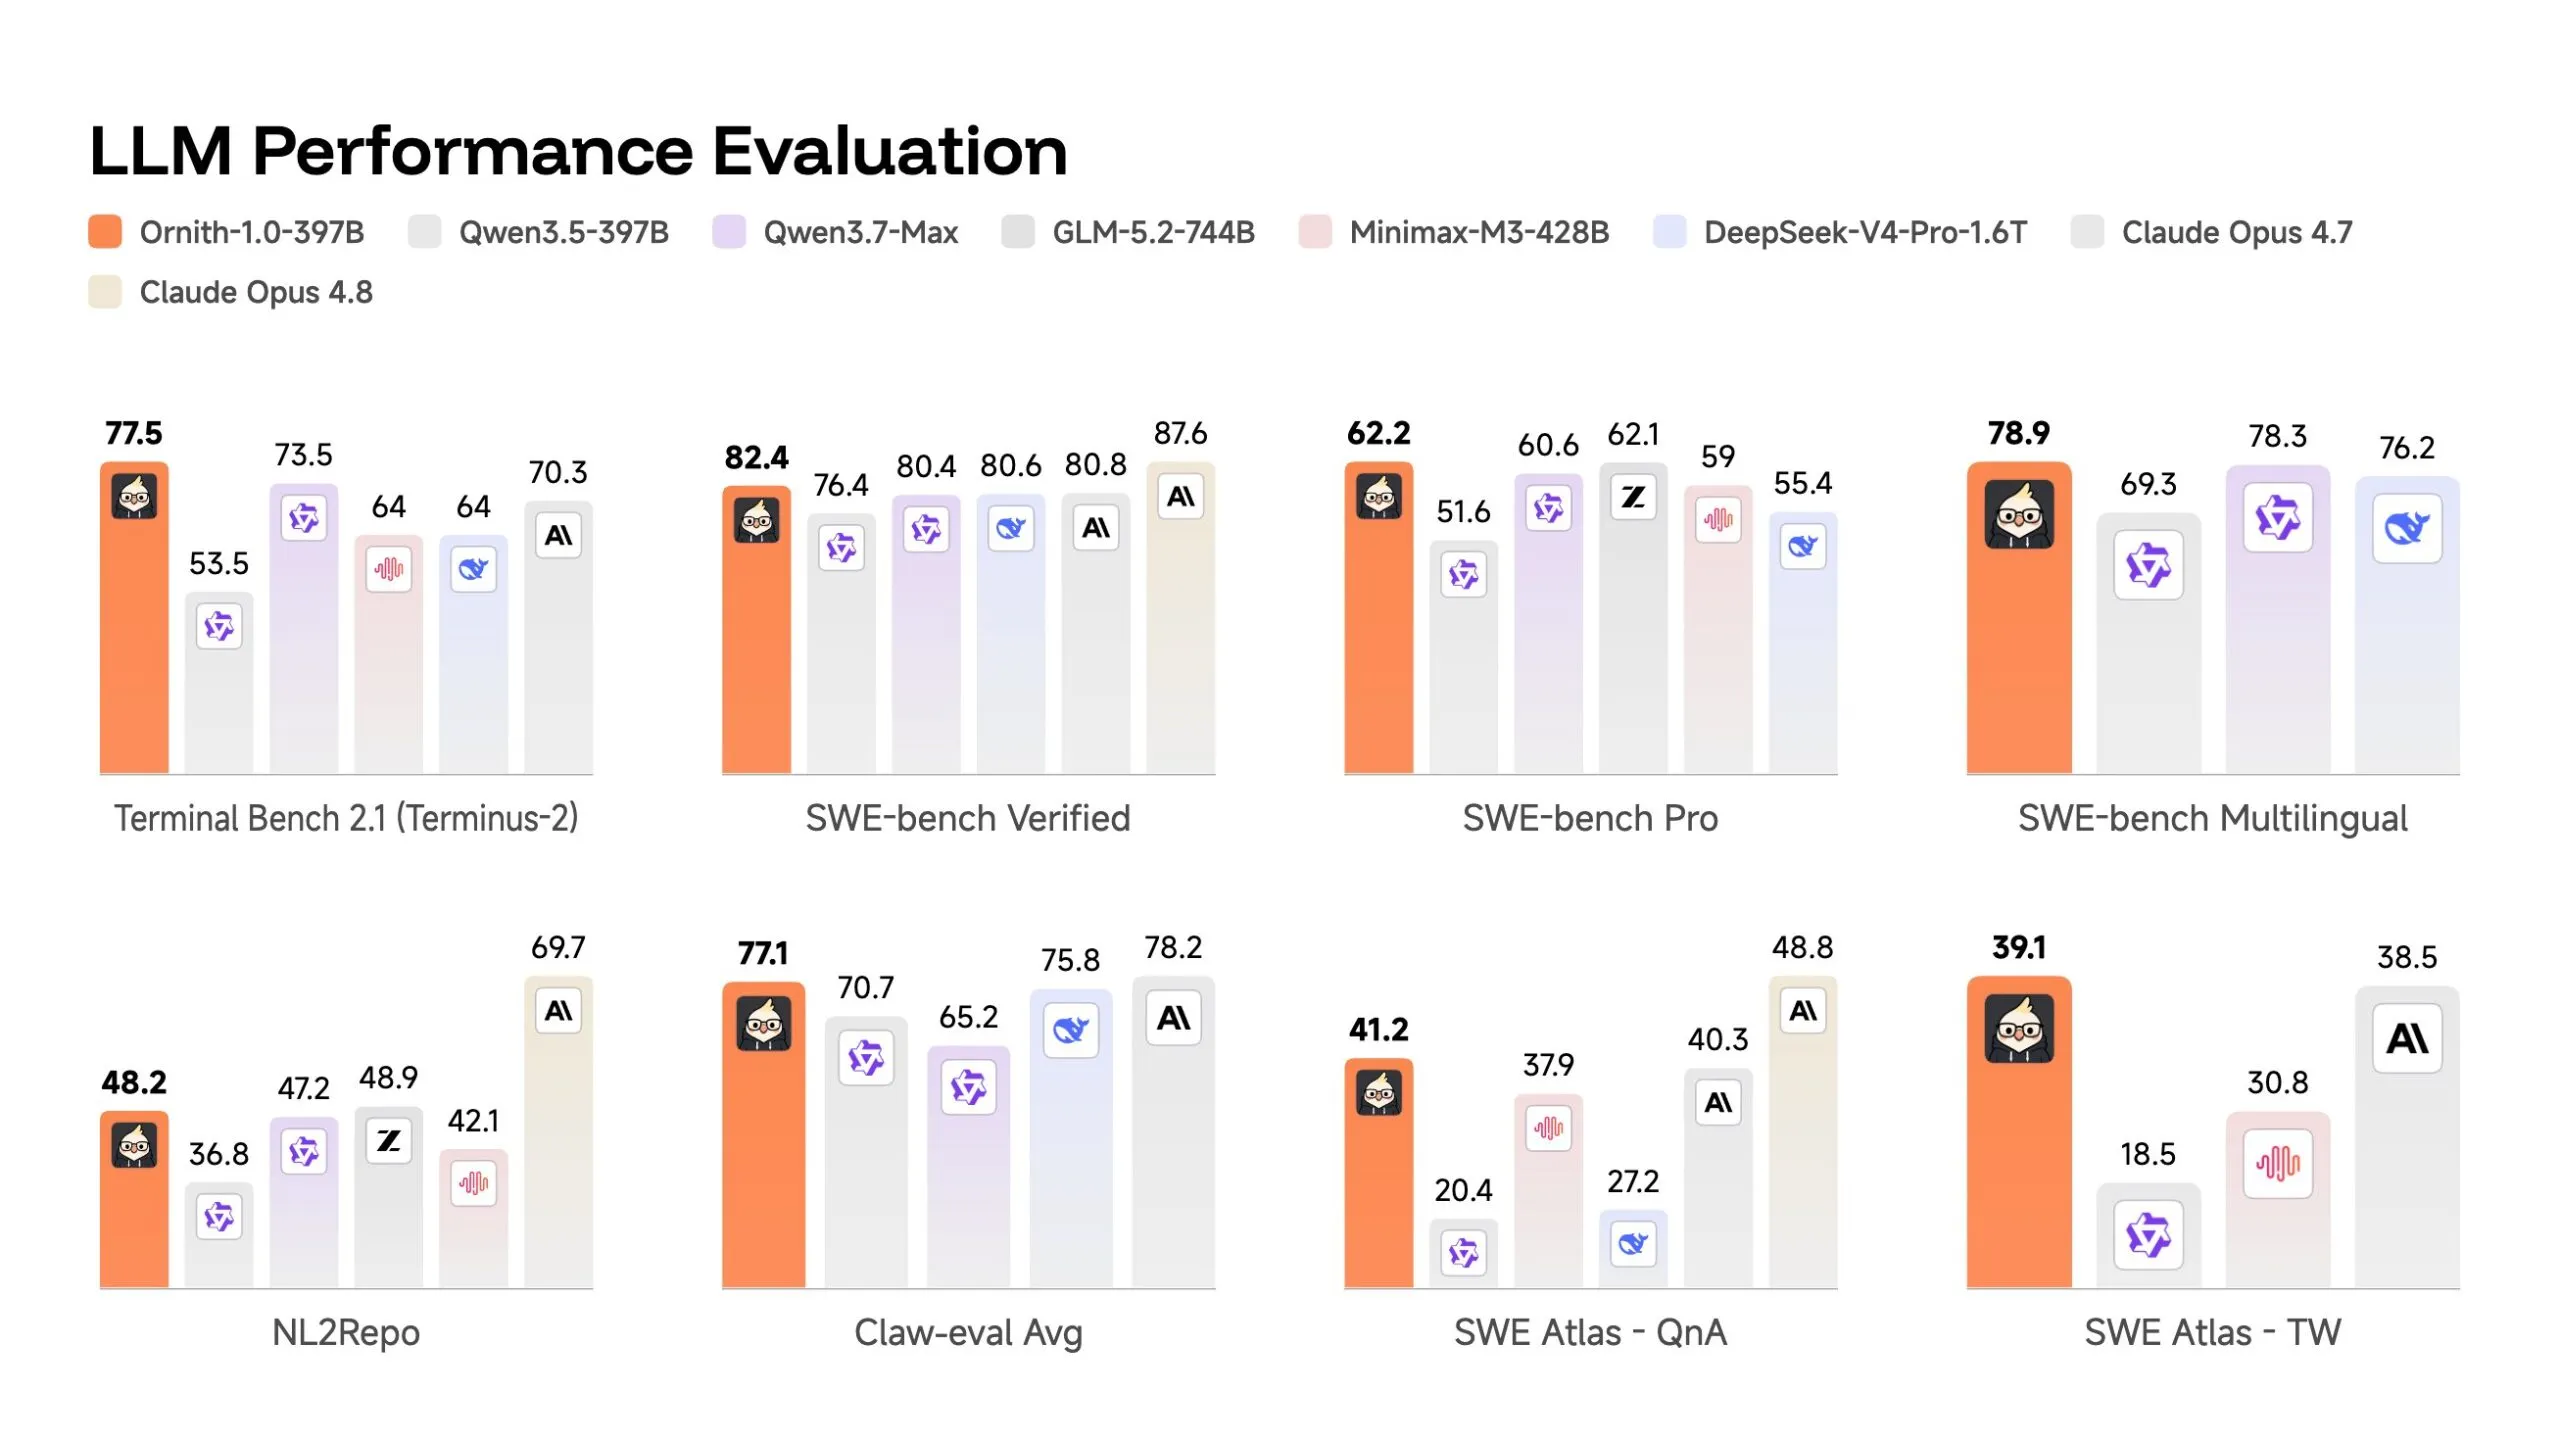
The flagship 397 billion parameter mannequin posts 82.4 on SWE-bench Verified—a take a look at the place an AI is given an actual bug from an open-source GitHub repository and should repair it with out seeing the take a look at suite, scored as the share of points it efficiently resolves.

That beats Claude Opus 4.7’s 80.8 and DeepSeek-V4-Professional’s 80.6 on the identical take a look at. On Terminal Bench 2.1—89 duties run inside containerized terminal environments starting from debugging async code to resolving safety vulnerabilities, scored by completion charge—it posts 77.5 towards Claude Opus 4.7’s 70.3.
Provided that SWE-bench contamination concerns have been raised publicly—OpenAI argued earlier this 12 months that fashions had been inflating scores by memorizing benchmark options seen throughout coaching—Ornith additionally experiences numbers on SWE-bench Professional, a more durable model utilizing extra various, less-leaked codebases scored the identical approach. The 397 billion mannequin lands at 62.2 there. Meaningfully decrease, however nonetheless aggressive with the sphere, and nonetheless higher than Deepseek V4 Professional.
The 9 billion parameter mannequin is perhaps the extra attention-grabbing information level. It posts 69.4 on SWE-bench Verified—greater than Gemma 4-31B’s 52 and aggressive with Qwen 3.5-35B’s 70, regardless of being 3-4 instances smaller.

Who it is for, and who it is not
Ornith-1.0 is explicitly not a general-purpose AI. The mannequin’s personal documentation says it could underperform on duties outdoors agentic coding. If you would like AI to summarize a doc, assist you to write your doctoral thesis, or draft an electronic mail, Ornith-1.0 is the flawed decide.
It is optimized for a slim downside set: developer pipelines the place an AI agent takes a job description, operates inside a code repository or terminal session, and completes multi-step work with out intervention. It is a software that was constructed for people who find themselves already operating agent infrastructure—not for folks making an attempt to determine if AI is value utilizing.
The “beats Claude” headline is actual however requires context. As Decrypt reported, each lab is now chasing efficiency on agentic coding evals, as a result of that is the place the helpful efficiency variations dwell.
Ornith-1.0-397B does surpass Claude Opus 4.7 on each totally different coding benchmarks, however Anthropic’s present flagship, Claude Opus 4.8, scores greater. The comparability that holds is inside the open-source class, at comparable parameter counts, on coding-specific agent duties.
For builders constructing self-hosted coding pipelines, agentic infrastructure, or related coding-focused work, the small and medium fashions operating on edge {hardware} could also be genuinely helpful, however the common Joe could also be higher wanting some other place.
Each day Debrief E-newsletter
Begin on daily basis with the highest information tales proper now, plus authentic options, a podcast, movies and extra.
You might also like
More from Web3
Coinbase Files to List Single-Stock Perps on Apple, Tesla and Nvidia
Briefly Coinbase filed with the CFTC by means of Coinbase Derivatives to record single-stock perpetual futures within the US, searching …
Zcash Is Running—Devs Want to Make It Faster
In short Zcash builders are focusing on Nov. 5 to activate NU7, an improve that cuts block time—the interval between …
OpenAI Models Are Writing Their Own Jailbreak Instructions—And Sometimes Obeying Them
In short OpenAI revealed a brand new misalignment reporting framework alongside six experiences documenting regarding mannequin habits it discovered over …