Briefly
- SpaceXAI launched Grok 4.5 on July 8 at $2 per million enter tokens and $6 per million output, lower than half the value of comparable fashions from Anthropic and OpenAI.
- Elon Musk posted on X that the mannequin is “roughly corresponding to Opus 4.7,” Anthropic’s earlier flagship, now outdated by Opus 4.8, whereas touting velocity and value over benchmark efficiency.
- Grok 4.5 isn’t obtainable within the EU but; SpaceXAI says European entry is anticipated in mid-July.
Elon Musk’s SpaceXAI launched Grok 4.5 on Wednesday, its first public mannequin for the reason that SpaceX-xAI merger closed in February and SpaceX’s pending $60 billion deal to amass Cursor. It targets coders, engineers, and what the corporate calls “data employees”—a class that apparently covers everybody from software program builders to legal professionals reviewing contracts to finance groups constructing Excel fashions.
The corporate’s pitch is not that it is the finest mannequin. It is that it is low-cost, for a western mannequin no less than. Grok 4.5 prices $2 per million enter tokens and $6 per million output. Claude Opus 4.8, Anthropic’s main flagship, runs $5 enter and $25 output. GPT 5.6 Sol, OpenAI’s new top-tier mannequin that additionally launched Wednesday, is priced at $5 enter and $30 output.
Musk posted on X and clarified the place his new mannequin really sits. He referred to as it “roughly corresponding to Opus 4.7, however a lot sooner.” Opus 4.7 is Anthropic’s earlier flagship; Opus 4.8 has since succeeded it. Claude Fable 5 is now Anthropic’s prime of the road providing.
He framed that as a deliberate tradeoff: velocity and value over uncooked functionality, with engineers at Tesla and SpaceX because the proof of real-world utility.
What the benchmarks really present
SpaceXAI revealed 4 benchmark outcomes at launch, and the image is combined. DeepSWE 1.1 measures how reliably an AI can shut actual software program bugs submitted by builders, utilizing a standardized testing setup so fashions may be in contrast pretty, scored by share of points mounted. Grok 4.5 scored 53%, behind Claude Opus 4.8 at 59% and GPT 5.5 at 67%. Claude Fable 5, Anthropic’s frontier mannequin, topped the chart at 70%.
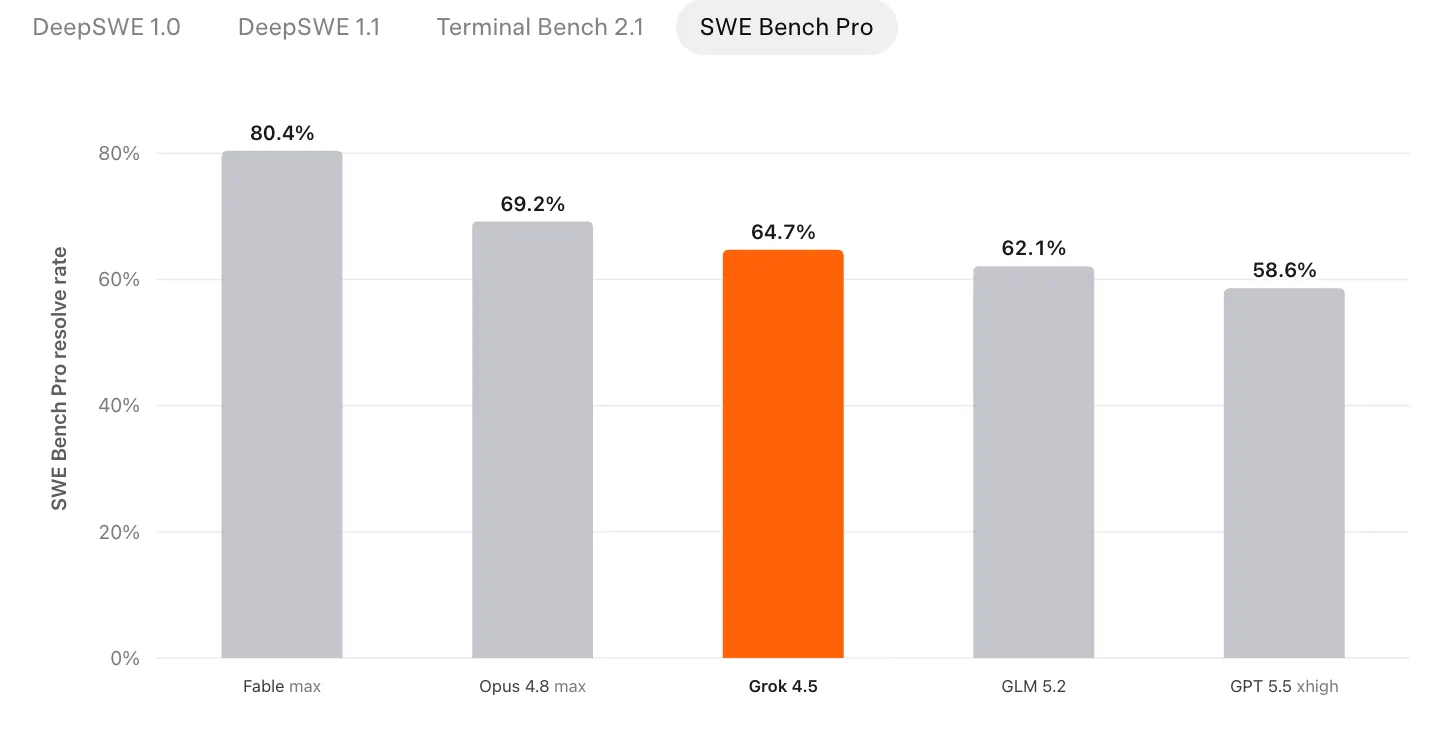
On SWE Bench Professional, one other benchmark that measures a set of software program engineering issues scored by decision fee, Grok 4.5 posted 64.7%, sufficient to beat GPT 5.5’s 58.6% on that specific take a look at. Opus 4.8 nonetheless leads at 69.2%, and Fable 5 sits at 80.4%.

The corporate’s benchmarks evaluate in opposition to GPT 5.5, not GPT 5.6, as a result of the latter additionally launched Wednesday, hours after Grok 4.5’s announcement.
SpaceXAI educated Grok 4.5 in collaboration with the just lately acquired Cursor AI on tens of 1000’s of Nvidia GB300 GPUs inside Colossus, the Memphis supercomputer with whole capability throughout greater than 200,000 GPUs. The labs whose fashions sit above it on those self same benchmarks do not personal something near that {hardware}. The mannequin that got here out is aggressive, simply not first.
That sample has adopted Grok across multiple releases. SpaceXAI has persistently turned up with monumental compute and third-place scores. What modified with Grok 4.5 is the pricing and the coaching sign.
The place the case for it really holds
The higher argument is not uncooked efficiency; it is effectivity math. On SWE Bench Professional duties, Grok 4.5 used a median of 15,954 output tokens to finish every job. Opus 4.8 burned by means of 67,020 tokens for a similar work, a 4.2x hole.
For groups operating AI at quantity, that distinction compounds into actual financial savings on prime of the already-lower value per token. Even with Grok 4.5 scoring so low within the high quality benchmarks, cheaper tokens and extra effectivity in utilization enable for extra iterations with out spending a lot.
The mannequin additionally runs at 80 tokens per second, which is fast-model territory. Grok 4.5 was educated on developer session information from Cursor, together with debugging traces and actual code edits moderately than static repositories. As Musk admitted in court, xAI’s coaching practices have drawn scrutiny earlier than; this time the pipeline runs by means of a platform SpaceX is within the course of of shopping for outright.
For builders operating high-volume coding duties, the mathematics works: roughly Opus 4.7 functionality at 60% much less per enter token. For anybody chasing the frontier, Claude Fable 5 leads each class SpaceXAI selected to publish. Our fast take a look at utilizing Grok construct on Hermes was underwhelming for inventive writing and acceptable on a easy coding process.
The mannequin is accessible through API, on Hermes and Grok construct with half 1,000,000 tokens of context (slightly bit lower than 400,000 phrases). European customers must wait earlier than utilizing it; SpaceXAI says Grok 4.5 reaches the EU in mid-July.
Each day Debrief Publication
Begin daily with the highest information tales proper now, plus unique options, a podcast, movies and extra.
You might also like
More from Web3
Coinbase Files to List Single-Stock Perps on Apple, Tesla and Nvidia
Briefly Coinbase filed with the CFTC by means of Coinbase Derivatives to record single-stock perpetual futures within the US, searching …
Zcash Is Running—Devs Want to Make It Faster
In short Zcash builders are focusing on Nov. 5 to activate NU7, an improve that cuts block time—the interval between …
OpenAI Models Are Writing Their Own Jailbreak Instructions—And Sometimes Obeying Them
In short OpenAI revealed a brand new misalignment reporting framework alongside six experiences documenting regarding mannequin habits it discovered over …